LongDiff: Training-Free Long Video Generation in One Go

Abstract

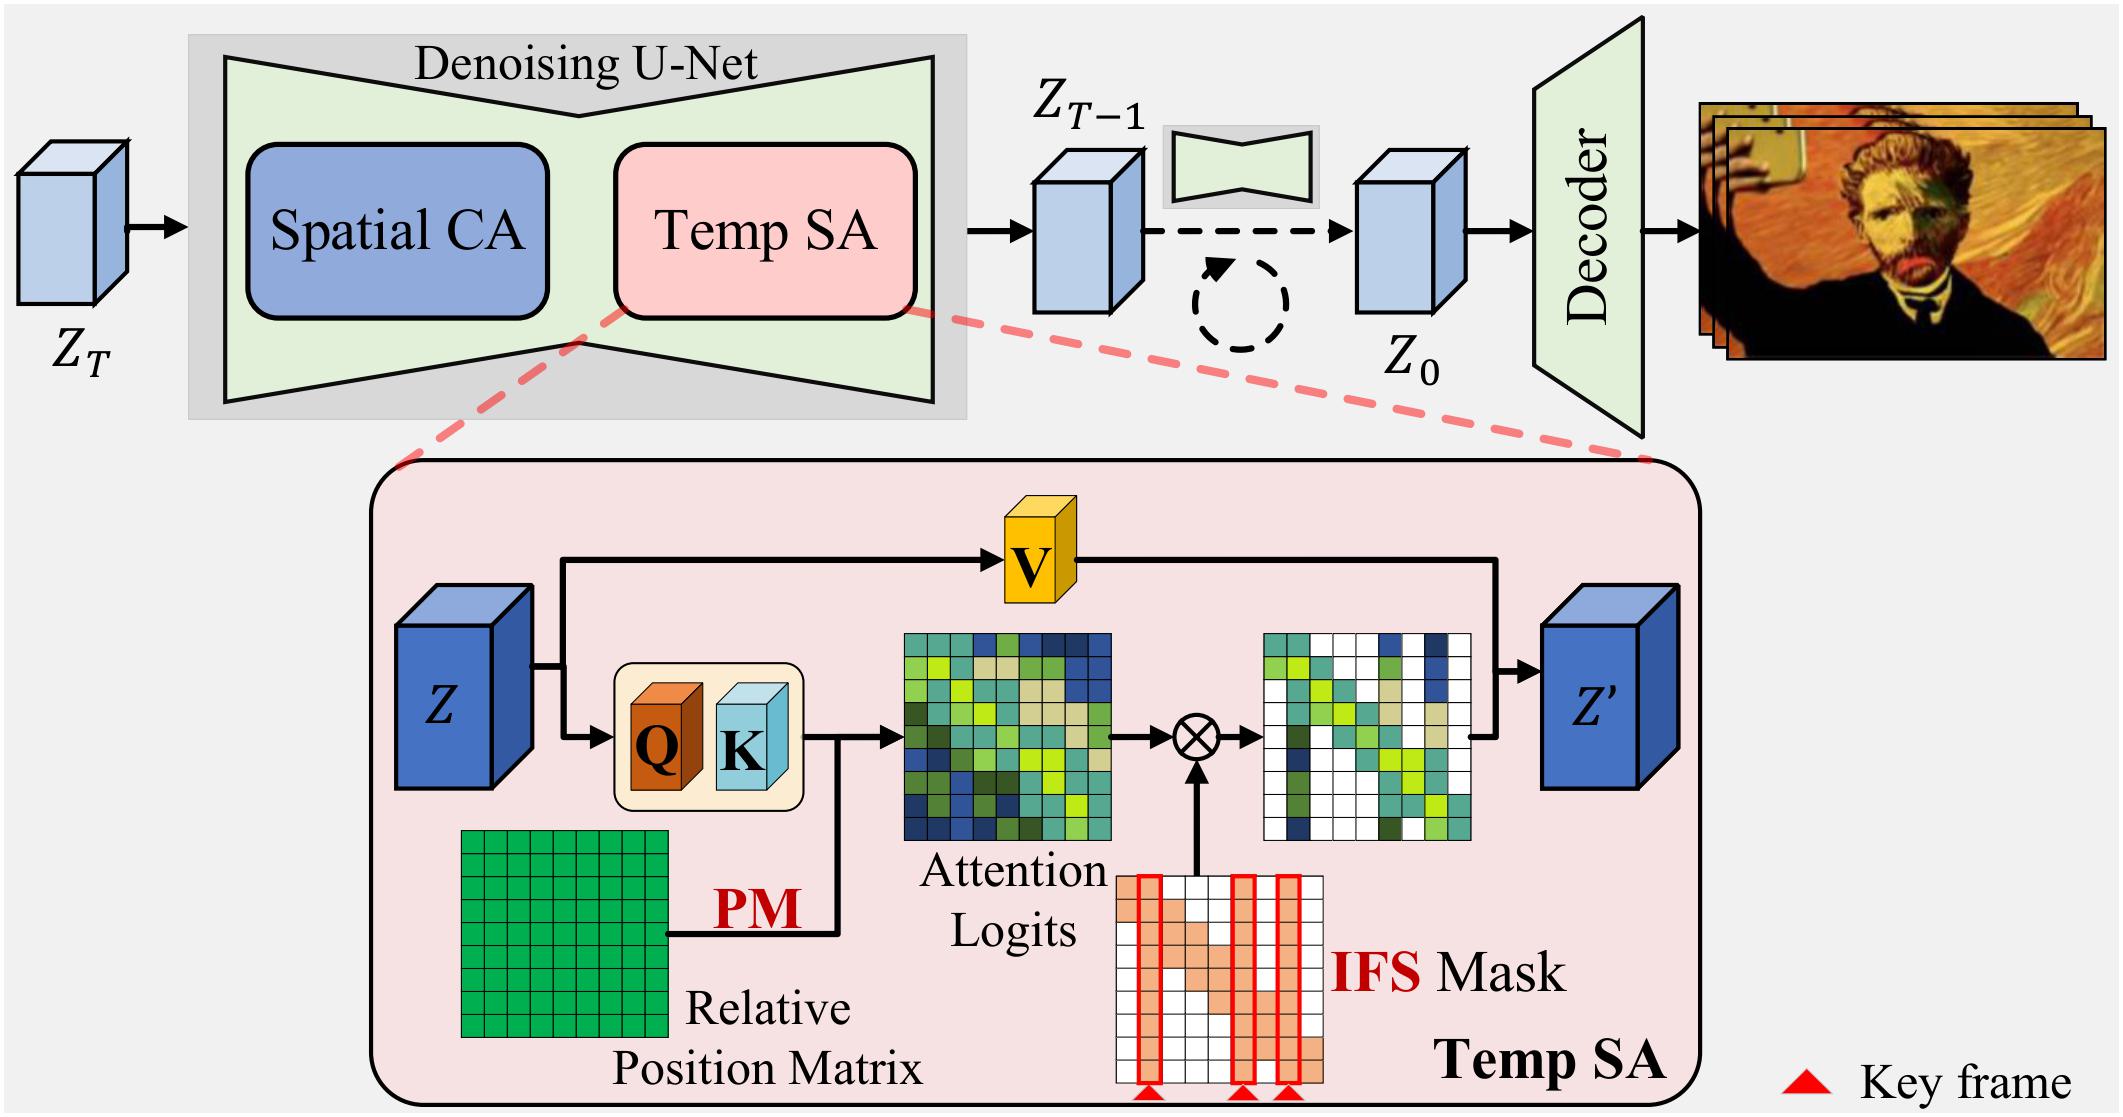
Video diffusion models have recently achieved remarkable results in video generation. Despite their encouraging performance, most of these models are mainly designed and trained for short video generation, leading to challenges in maintaining temporal consistency and visual details in long video generation. In this paper, through theoretical analysis of the mechanisms behind video generation, we identify two key challenges that hinder short-to-long generalization, namely, temporal position ambiguity and information dilution. To address these challenges, we propose LongDiff, a novel training-free method that unlocks the potential of the off-the-shelf video diffusion models to achieve high-quality long video generation in one go. Extensive experiments demonstrate the efficacy of our method.

Ablation Study of the Main Components of LongDiff

Prompt: a polar bear playing drum kit in NYC Times Square, 4k, high resolution

w/o PM
w/o IFS
Ours

Qualitative Comparison with Other Methods

Prompt: video of yacht sailing in the ocean

Direct
Sliding
FreeNoise
FreeLong
Ours

Prompt: a footage of a frozen river

Direct
Sliding
FreeNoise
FreeLong
Ours

Prompt: a zebra eating grass on the field

Direct
Sliding
FreeNoise
FreeLong
Ours

Prompt: a red panda eating leaves

Direct
Sliding
FreeNoise
FreeLong
Ours

Prompt: people putting christmas ornaments on a christmas tree

Direct
Sliding
FreeNoise
FreeLong
Ours

Longer (256-frame) Video Generation

Prompt: dropping flower petals on a wooden bowl

Multi-Prompt Video Generation

Prompt 1: A waterfall flows in the mountains under a clear sky

Prompt 2: A waterfall flows in the fall mountains under a clear sky

Prompt 1: There is a beach where there is no one

Prompt 2: The waves hit the deserted beach

Prompt 3: There is a beach that has been swept away by waves